Some data can’t leave the building.
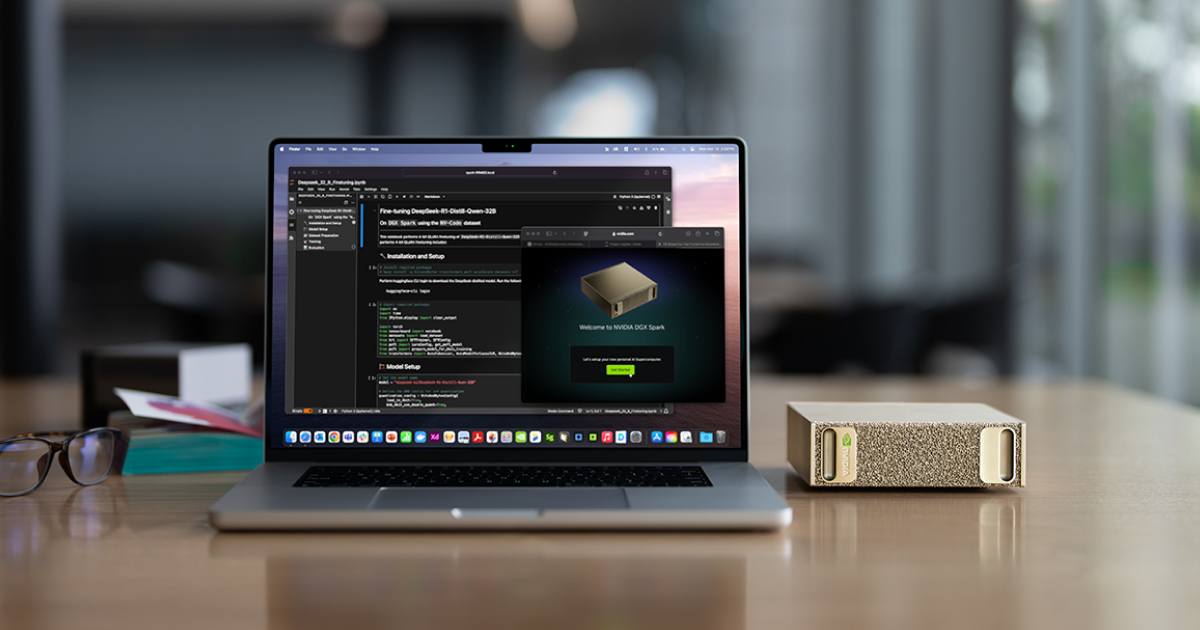
So we don’t ask it to. Privatus ships a GPU node that runs your AI inside your own walls — pre-installed with the model you choose, and able to work with no connection to the outside world at all.
- 0
- Outbound connections needed for inference
- 128 GB
- Unified memory on a single node
- ~10
- Concurrent users served per node
- 24/7
- Yours outright, idle hours included
The cloud answer doesn’t fail here on performance. It fails on permission.
Three sectors share one constraint: the data that would make AI most useful to them is the data they are least allowed to send anywhere.
Public administration
Citizen records, procurement files and case histories are bound by law to stay under your control. A node inside the building keeps processing within your own jurisdiction, so there is no cross-border transfer to document and defend.
Healthcare
Clinical notes are the hardest data in any organisation to send somewhere else. On-premise inference removes the third-party processor from the chain entirely: no patient record leaves the network in order to be read, summarised or classified.
Defense
Where an outbound connection is not a risk to be managed but a prohibition, the node runs disconnected. Air-gapped operation is the default state of the machine rather than a setting you have to audit and trust.
On-premise is the only guarantee that isn’t a promise.
Every other arrangement asks you to trust a contract about somebody else’s servers. We take the servers out of the equation and put one in your building instead.
You choose the model
We are provider-agnostic. Whatever is strongest for your task goes on the node — a general-purpose model, a domain-tuned one, image generation. Nothing about the box commits you to a vendor.
We build the node
CANDY, our platform, is installed on the GPU alongside your model and connected to the data sources you already run. The node is configured, benchmarked and validated before it ships.
You plug it in
It arrives ready to work. Ethernet or USB, inside your own network. Inference needs nothing from the outside, so nothing you process is ever transmitted anywhere.
It stays current
Models move faster than procurement cycles. CANDY can update or swap the installed model over time, so the node doesn't age out when the next generation lands. The hardware is the only real ceiling.
The whole thing arrives in one box.
An Nvidia GPU node small enough to sit beside a workstation, with enough memory to run a serious model locally. We build the application around your needs, install it alongside the model, and send you hardware that works the moment it has power.
- Unified memory
- 128 GB
- Connectivity
- Ethernet / USB
- Internet required
- None for inference
- Form factor
- Desktop class
- Concurrent users
- ≈10 per node
Concurrency measured with continuous batching on a 27B-class model. Real figures depend on the model installed and your context lengths, so we benchmark per deployment.
Air-gap capable
Inference needs no outbound connection at all. The node can be fully disconnected and keep working, which is what strict compliance regimes actually ask for — not an assurance that traffic is encrypted in transit.
Sized against measurements, not brochures
One node comfortably serves around ten people working at once. Before we quote, we measure throughput on your own documents and your own question load, so the number you are given is yours.
Yours around the clock
Nobody bills you per token, so the sixteen idle hours every night are free capacity: indexing new archives, pre-summarising long dossiers, producing the reports that are waiting when the office opens.
A model on its own isn’t a working system.
CANDY is the software that turns the node into something your staff use on a Tuesday afternoon without thinking about it. Every part of it runs inside your perimeter, with no third-party service anywhere in the path.
Complex file handling
Ingest the formats your organisation actually runs on — long PDFs, scans, spreadsheets, mixed archives — into private libraries that never leave the node.
Multi-model workflows
Chain several models into one pipeline and manage the full lifecycle of each job, from submission through review to completion, with custom input and output handling.
Dynamic and admin dashboards
A working dashboard for your teams and an administrative console with runtime status, execution history and health diagnostics. Self-contained, with nothing phoning home.
Identity and access control
Self-hosted authentication with OAuth and magic links, paired with user roles and access control, so the right people reach the right documents and nobody else does.
Internal token system
Allocate and track usage per user or department on an internal ledger. Useful for governance and capacity planning, and it bills nobody, because the hardware is already yours.
Notifications and handoffs
Email notifications move work between people and keep long-running jobs visible, so a queued analysis doesn't quietly stall waiting for someone to check a screen.
Start with the constraint, not the demo.
Tell us which data you are not allowed to send anywhere and how many people need to work with it. That is enough for us to say what a node would have to do — and whether one is enough.
Get in Touch
Having a technical issue? Want to send us feedback on a beta feature? Or do you need information about our Business plan? Let us know!